


Think about the last time you pasted a heavy document into ChatGPT or Claude. Maybe it was a contract, a research paper, or a full quarter’s worth of meeting notes. You hit enter and waited. The response came back slower than usual, or the model seemed to lose track of what you said at the top. Maybe it just stopped mid-sentence.
That was not the AI being lazy. That was a memory problem.
Every time an AI model responds to you, it needs to hold your entire conversation in working memory while it generates an answer. Every word you have typed, every document you have uploaded, every instruction you have given, all of it has to stay loaded and accessible at once. The longer and more complex the conversation, the more memory it demands. And when the memory runs out, the model either slows down, starts forgetting context, or simply hits a wall.
The chip responsible for that working memory is called High Bandwidth Memory, or HBM. It is arguably the most important component in AI infrastructure that most people have never heard of. The reason everyone talks about Nvidia and not about HBM is roughly the same reason everyone knows the name of the car but not the name of the fuel. One gets the credit. The other does the work.
That slowdown is not new, and it is not unique to AI. Computer scientists have a name for it. They call it the memory wall, a concept first described in 1995 by an IBM researcher named William Wulf, who predicted that processor speeds would eventually outpace memory speeds so dramatically that the most powerful chips in the world would spend most of their time doing nothing, just waiting for data to arrive.
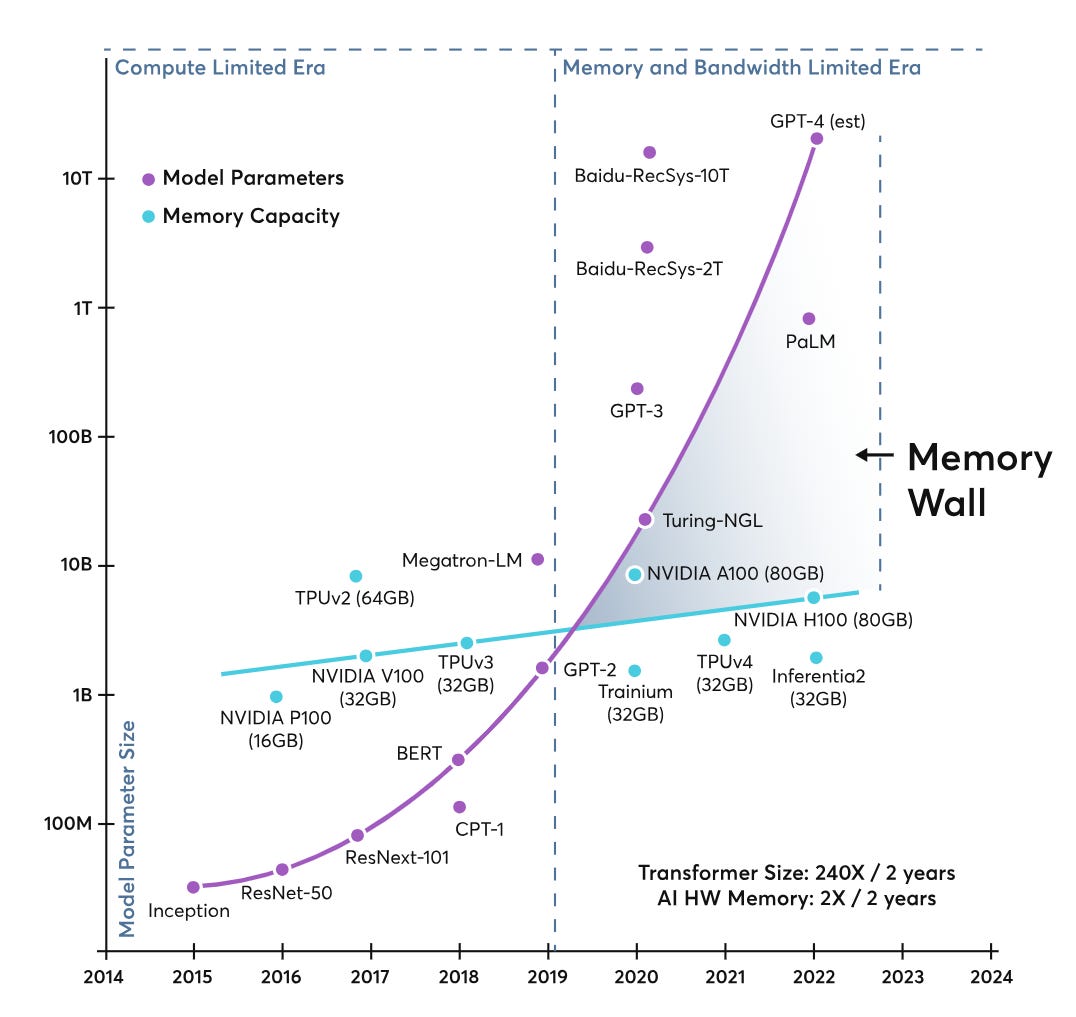
The analogy that keeps coming up among people who study this is a kitchen. Imagine you have a chef who can chop a thousand onions per minute. Extraordinary speed. But the refrigerator where the onions are stored is across the room, and the assistant bringing them over can only carry one at a time. The chef is not slow. The delivery system is the constraint. That is what happens inside a GPU like Nvidia’s H100: the processor can perform hundreds of trillions of operations per second, but many AI workloads are bottlenecked not by compute, but by how fast memory can deliver the data. HBM is the industry’s answer to that problem. Instead of sending data across a long, narrow path, you stack the memory directly on top of the processor, connected by thousands of microscopic vertical wires, so the data barely has to travel at all.
Only three companies in the world can do it at scale: SK Hynix and Samsung in South Korea, and Micron in the United States. The reason there are only three has everything to do with how extraordinarily difficult the chip is to manufacture. All three have already sold out their entire 2026 production (more on CNBC). And the forces driving demand are not easing. They are accelerating.
What HBM actually is, and why almost nobody can make it
To understand what HBM does, start with something you already know. Your phone has two kinds of memory. One is storage, the place where your photos and apps live permanently. The other is RAM, the working space your phone uses when it is actually running something. Storage is the filing cabinet. RAM is the desk.
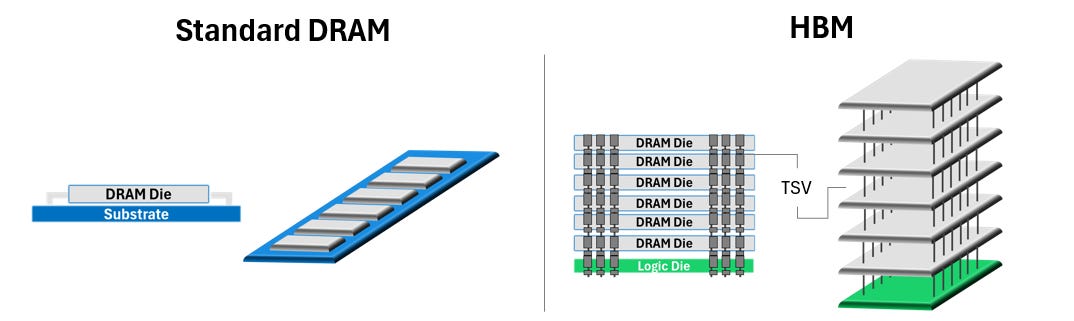
HBM is a specialized, extreme version of that desk, purpose-built for AI. It sits physically inside the processor package, not across a circuit board or in a separate module, but right next to the GPU itself. The way it gets there is what makes it so difficult to produce. HBM is not a single flat chip. It is a stack of multiple memory layers built on top of each other and connected by thousands of microscopic vertical wires called through-silicon vias. Each layer has to be nearly perfect, because a single defect in one can compromise the entire stack.
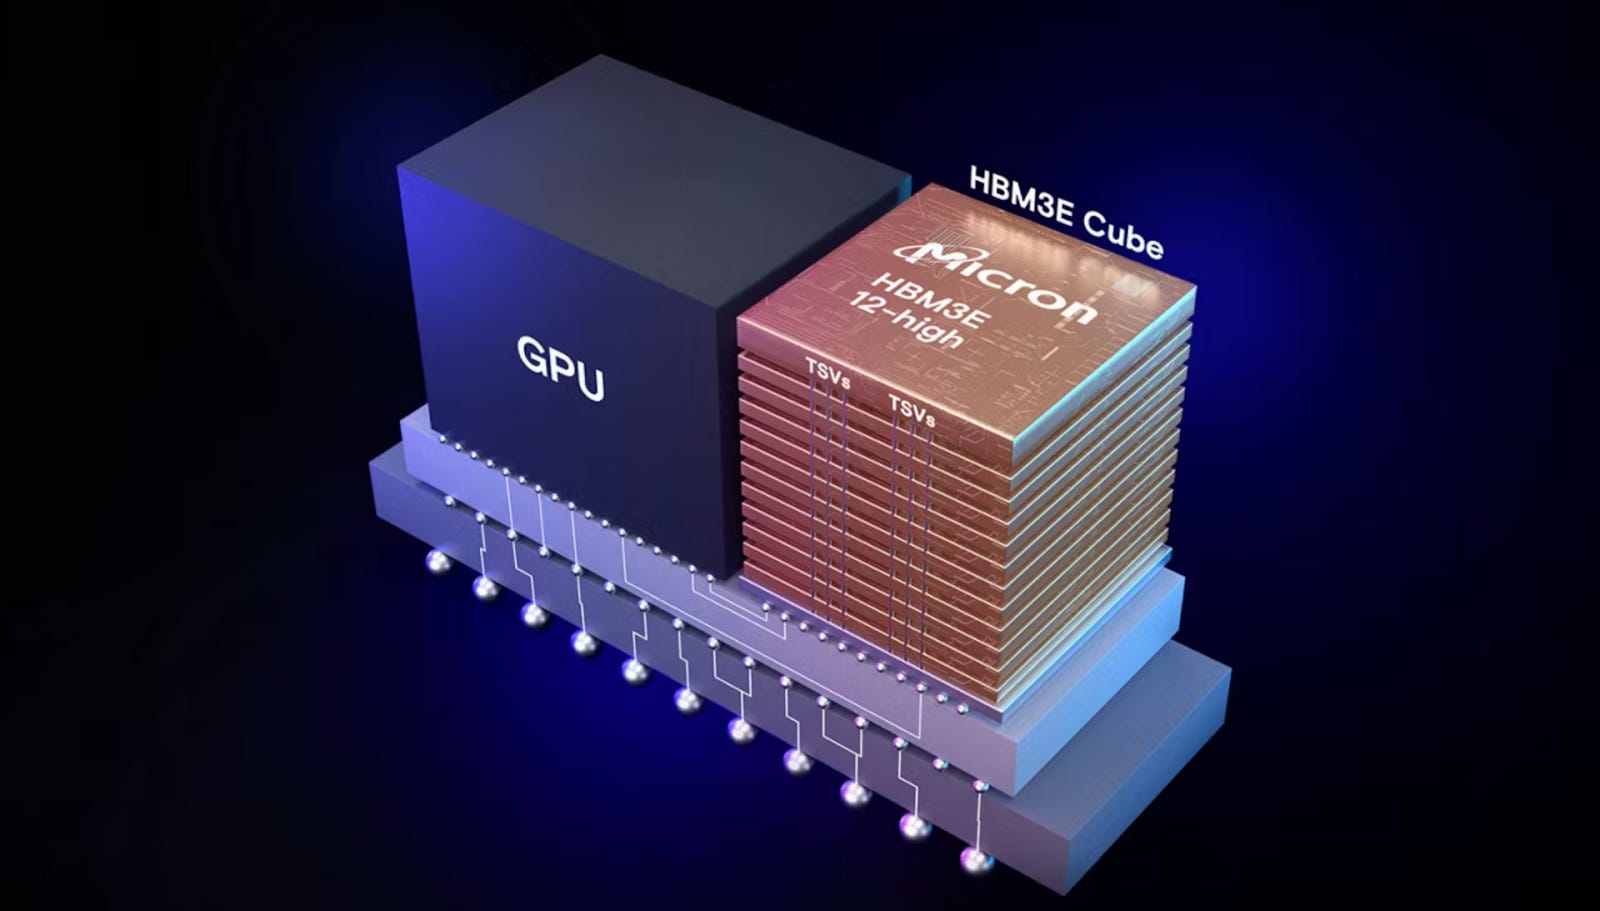
The stacking process is where most of the difficulty lives. Each layer has to be nearly perfect. A single defect in one die can compromise the entire stack, which means yields—the percentage of chips that actually work after manufacturing—are punishingly hard to maintain. The packaging infrastructure required to assemble these stacks at scale barely exists outside a handful of facilities worldwide. It took decades of process development to get here, and the gap between the companies that can do it and the companies that cannot is not closing. China’s most advanced memory producer, CXMT, is currently shipping a product roughly equivalent to what Korean manufacturers were making in 2016 (more on DigiTimes).
The market share breakdown tells you a lot about the dynamics between the three. SK Hynix leads with roughly 62% of the global HBM market. Micron holds about 21%. Samsung, despite being the largest memory company in the world by overall revenue, trails at around 17%, in part because it has struggled to meet Nvidia’s thermal and performance requirements for its latest chips (more on Mark LaPedus’s Substack). SK Hynix is Nvidia’s preferred supplier and has been for years. Micron is the only American producer. Samsung is the giant that, in this particular race, is playing catch-up.
A Spanish-language investing podcast I follow put it in terms that stuck with me: Nvidia has the name, software companies have the hype, but there are three factories that, if they stopped tomorrow, would paralyze the progress of artificial intelligence globally. The market for HBM is worth roughly $35 billion today and is projected to reach $100 billion by 2028. Every major hyperscaler, from OpenAI to Google to Meta, has locked in long-term supply agreements years in advance just to guarantee access to something most of their users have never heard of (more on El Arte de Invertir).
Why the bottleneck keeps getting worse
In 2023, the leading AI models could hold somewhere between 8,000 and 100,000 tokens of context in a single conversation. A token is roughly three-quarters of a word, so that meant the model could work with something between a long memo and a short book before running out of room (more on Thinkpeak). Today, context windows of one million tokens or more are standard among frontier models. Google’s Gemini can hold two million. That is the equivalent of handing the model a full novel, a quarterly earnings report, and a codebase all at once, and asking it to reason across all of them simultaneously.
Every one of those tokens has to be held in working memory while the model generates a response. The technical term for this is the KV cache, essentially the model’s short-term memory during a conversation. It stores a compressed representation of every word in the context so the model can refer back to any part of it at any point. For a large model, the KV cache alone can consume more memory than the model’s own weights. And it grows with every message, every uploaded document, every additional instruction. The more you ask the model to hold in its head, the more memory it needs.
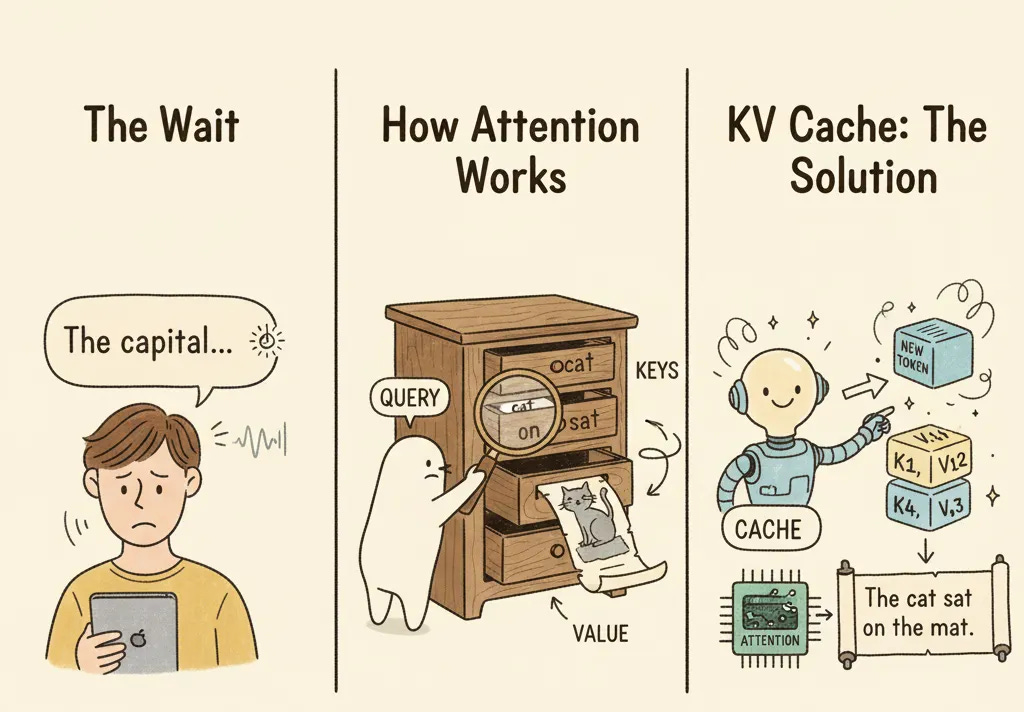
This is the structural problem at the center of the story. AI is not just getting smarter. It is getting hungrier. Every improvement in capability, longer context, more complex reasoning, more detailed outputs, translates directly into more memory demand per inference. The constraint does not ease as models improve. It compounds.
And it is not just context windows driving this. The infrastructure commitments being made right now reflect a demand curve that is accelerating, not flattening. OpenAI’s Stargate project alone has signed commitments for 900,000 DRAM wafers per month from Samsung and SK Hynix (more on OpenAI). NVIDIA’s next-generation Vera Rubin GPU will require nearly triple the memory bandwidth of its predecessor. Each new generation of hardware needs more HBM per chip, and each new generation of models needs more chips per deployment. The math moves in one direction.
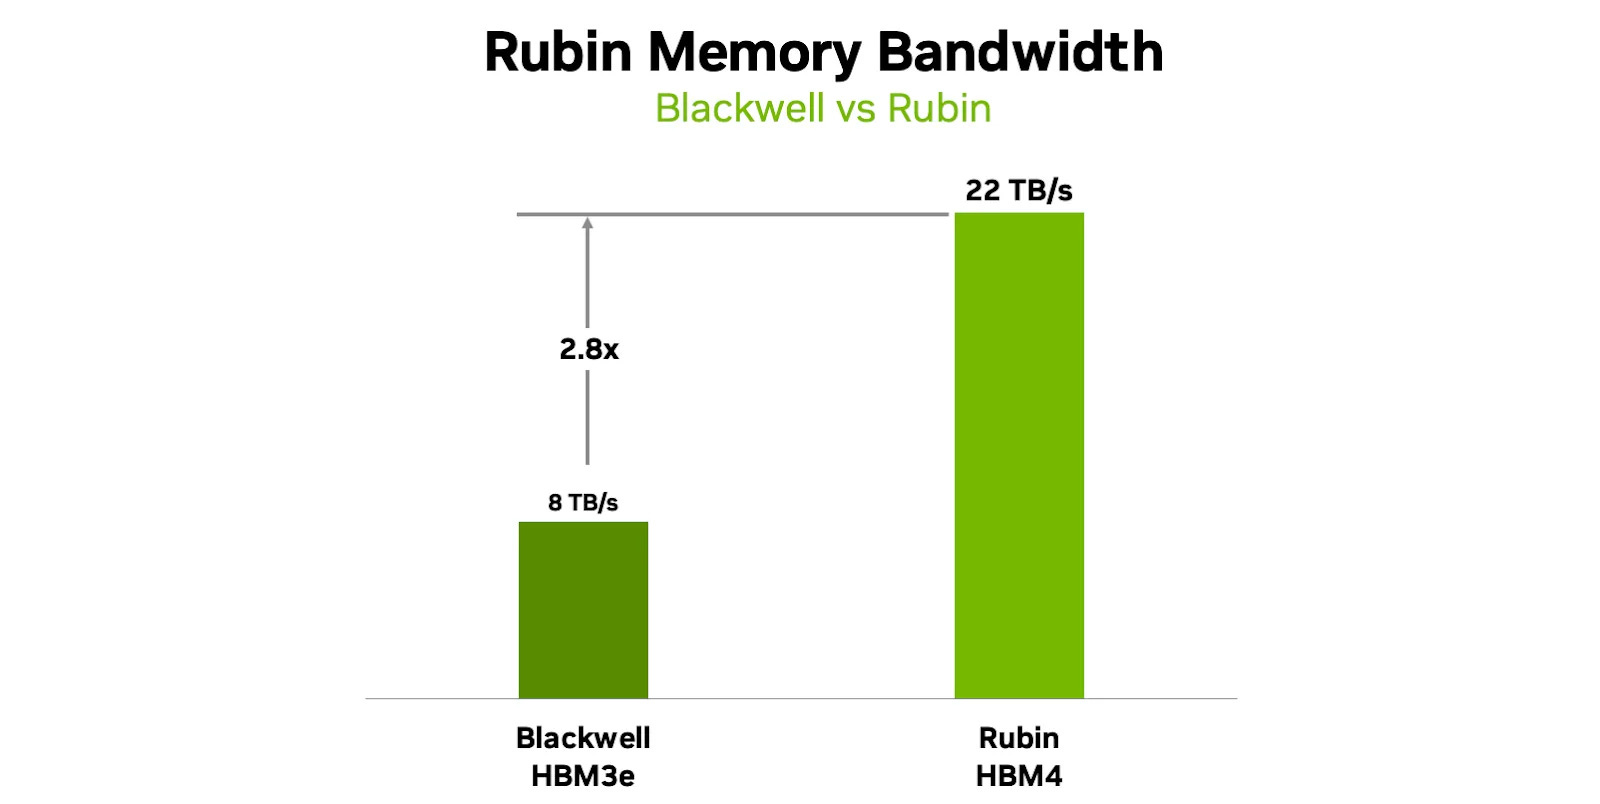
The HBM market was worth roughly $35 billion in 2025. Industry projections place it at $100 billion by 2028. That kind of growth rate, roughly 40% annually, is not speculative. It is the direct consequence of a simple fact: you cannot run the AI models the industry is building without the memory to feed them, and the memory does not exist yet in the quantities required.
The supply response, and why it takes so long
All three HBM producers are spending aggressively to expand capacity. The problem is that building a leading-edge memory fab costs upward of $15 billion and takes three to five years from investment decision to volume output, and no amount of urgency changes the timeline much.
SK Hynix, the market leader, accelerated construction of its M15X fabrication facility by four months and began HBM4 production in February 2026. It has committed an additional $15 billion toward its Yongin campus in South Korea through 2030 (more on Reuters). Samsung is expanding its Pyeongtaek P4 and P5 facilities, with P5 now targeting late 2027 instead of 2028, and aiming for a 50% increase in production capacity this year. Samsung’s challenge is not just building fast enough. It is building well enough. The company has struggled to meet Nvidia’s thermal and performance specifications, which is a significant part of why it trails SK Hynix despite being the larger company overall (more on CNBC).
Micron’s bet has been the most dramatic. In December 2025, the company exited the consumer memory market entirely to redirect all of its capacity toward AI and enterprise customers. It acquired a fabrication facility in Taiwan to accelerate its production timeline and is building a new complex in New York that will not reach full production until 2030. Micron is also the only American producer of HBM, which gives it a strategic dimension that extends beyond market share. As US export controls on advanced memory tighten and the conversation around supply chain resilience intensifies, Micron’s position becomes as much a policy story as a business one.
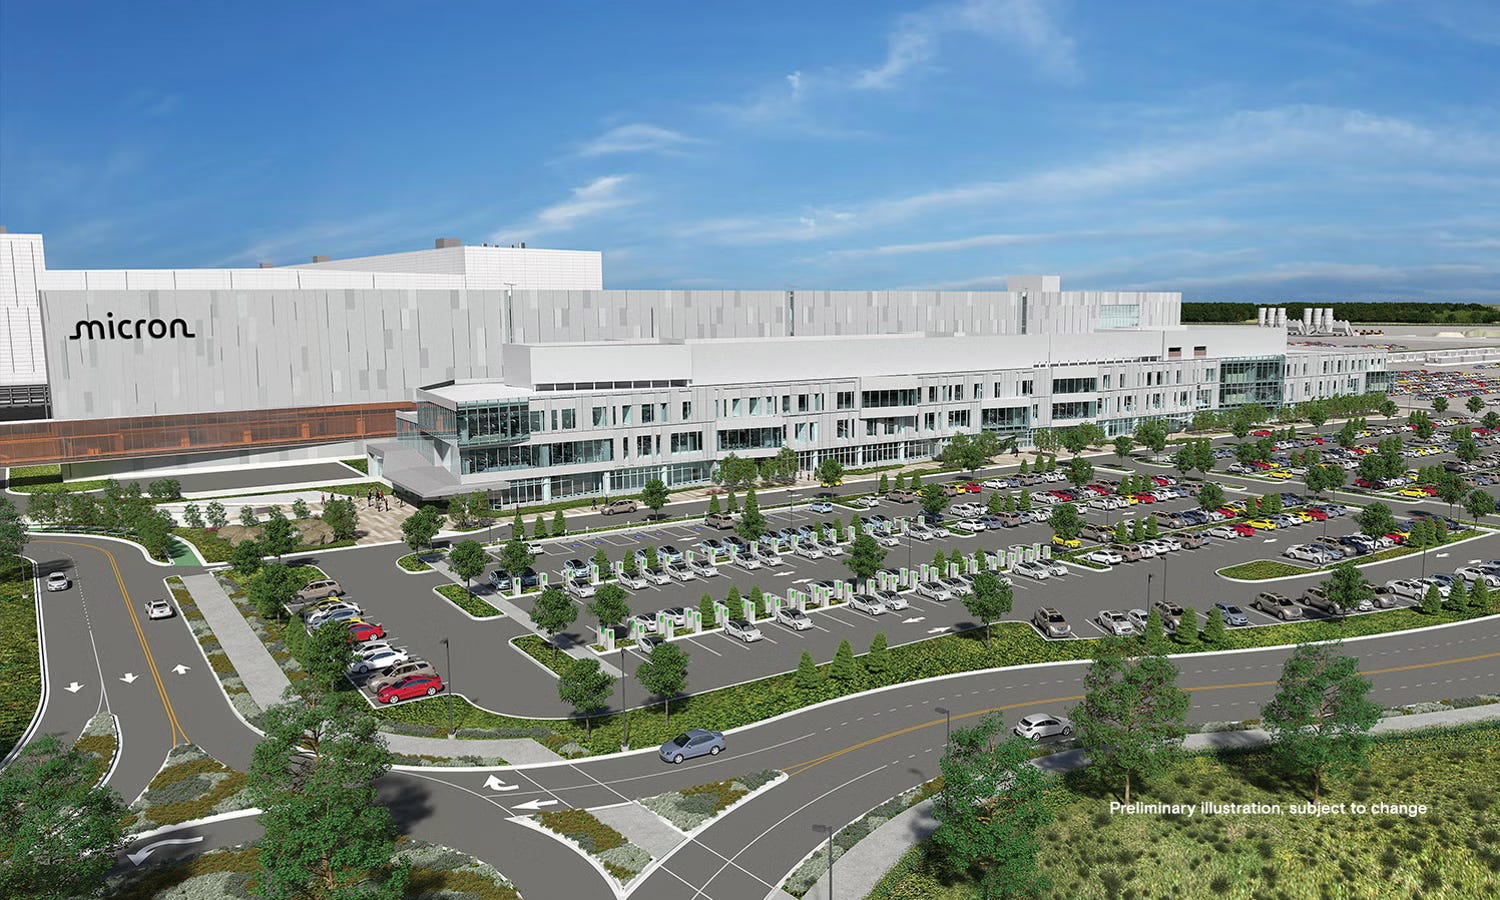
Even with all of this underway, industry consensus places meaningful supply relief no earlier than 2028, said Intel’s CEO (more on Bloomberg).
There is also a consequence that most coverage of the HBM race overlooks. Making HBM is not just harder than making regular memory. It is also far more resource-intensive. DRAM, the working memory that runs everything from cloud servers to laptops, is the base material that HBM is built from. But one gigabyte of HBM requires roughly three times the silicon wafer input of one gigabyte of conventional DRAM (more on Tom’s Hardware). So when all three producers shifted their factories toward HBM, they were not just prioritizing one product over another. They were consuming three times the raw material per unit for the product they chose to focus on, which meant everything else they used to make, regular server memory, flash storage, started running short, too. Not because demand for those products disappeared, but because the capacity to make them got absorbed into the HBM buildout.
The market figured it out before most people did
The most surprising consequence of the HBM shortage didn’t show up in HBM stocks. It showed up in a company most AI investors weren’t even watching.
If you had to guess which company benefited most from the AI memory boom, you would probably name one of the three HBM producers. You would be wrong.
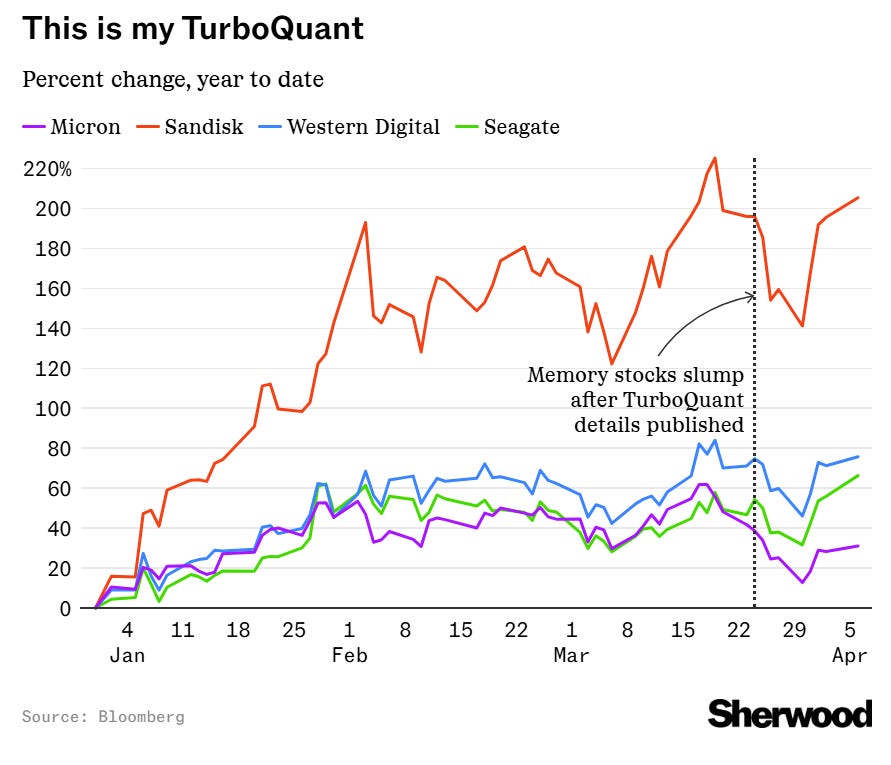
SanDisk is not an HBM company. It does not make the high-speed working memory that sits inside AI processors. It makes NAND flash, the storage layer, the kind of memory used in solid-state drives, USB sticks, and data center storage arrays. It is, by any measure, the least directly connected to artificial intelligence of any major memory company.
In February 2025, SanDisk spun out of Western Digital and began trading as an independent company at roughly $30 per share. It was the S&P 500’s best-performing stock in 2025, up 577%. Then it did it again in 2026, up another 296% year-to-date. From $30 to $943 in a single year. Most people have a SanDisk USB stick in a drawer somewhere. Almost nobody had it in their portfolio.
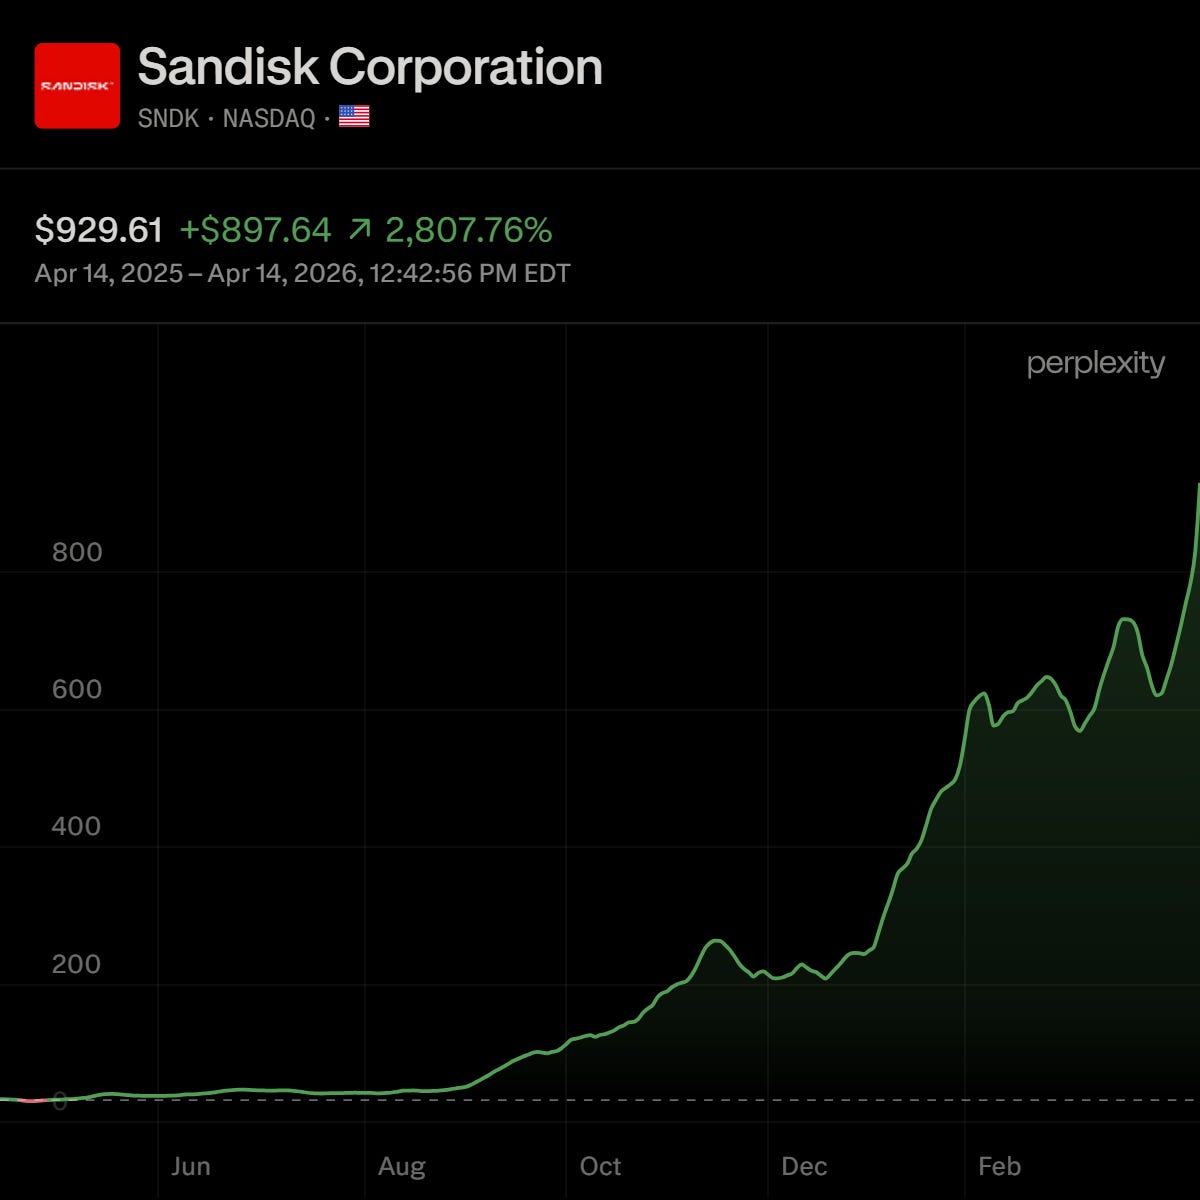
The reason is the ripple effect described above. When Samsung, SK Hynix, and Micron redirected their wafer capacity toward HBM, they pulled production away from conventional DRAM and NAND flash. NAND supply tightened across the industry. Prices surged. And SanDisk, which had done nothing differently, found itself holding pricing power in a market that was short on supply because everyone else had pivoted away.
The investing podcast I mentioned earlier captured the irony well: the company that has risen the most is the one that is less needed by AI, but that was left standing in a market where everyone else walked out of the room. It is the clearest illustration of how concentrated and fragile the memory supply chain really is. One strategic shift by three companies created a shortage in a completely adjacent market, and the biggest winner was a company that most AI investors were not even watching.
That kind of second-order outcome is what makes the memory bottleneck different from a typical supply constraint. It is not a single chokepoint. It is a system where every reallocation of resources creates a new imbalance somewhere else.
Can software solve a hardware problem?
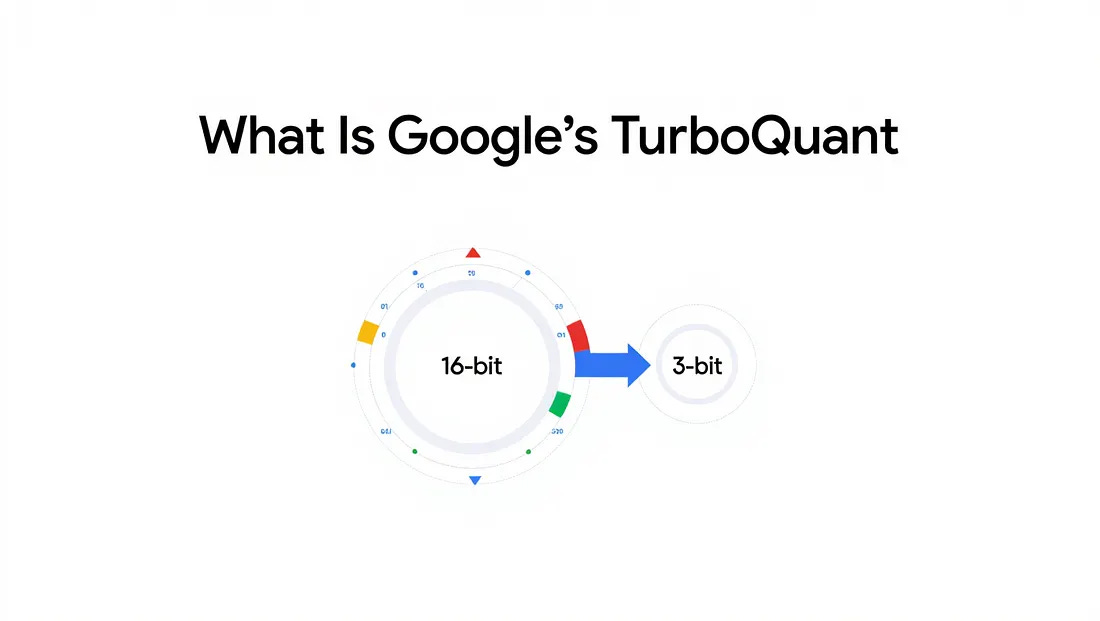
In March 2026, Google Research published a paper called TurboQuant. The claim was striking: a compression algorithm that could reduce an AI model’s working memory needs during a conversation by up to six times, without retraining the model, without any calibration data, and without measurably changing the quality of the output. Memory stocks fell within hours.
To understand why, go back to the KV cache from earlier in this piece. Every time you have a conversation with an AI model, the KV cache stores a compressed representation of every token the model has processed so far, so it can refer back to anything you’ve said at any point. The longer the conversation, the bigger the cache, the more memory it consumes. What TurboQuant does is compress that cache from the standard 16 bits per value down to about 3, which is where the six-times reduction comes from. Independent developers who tested it on several open-source models confirmed that the results hold up.
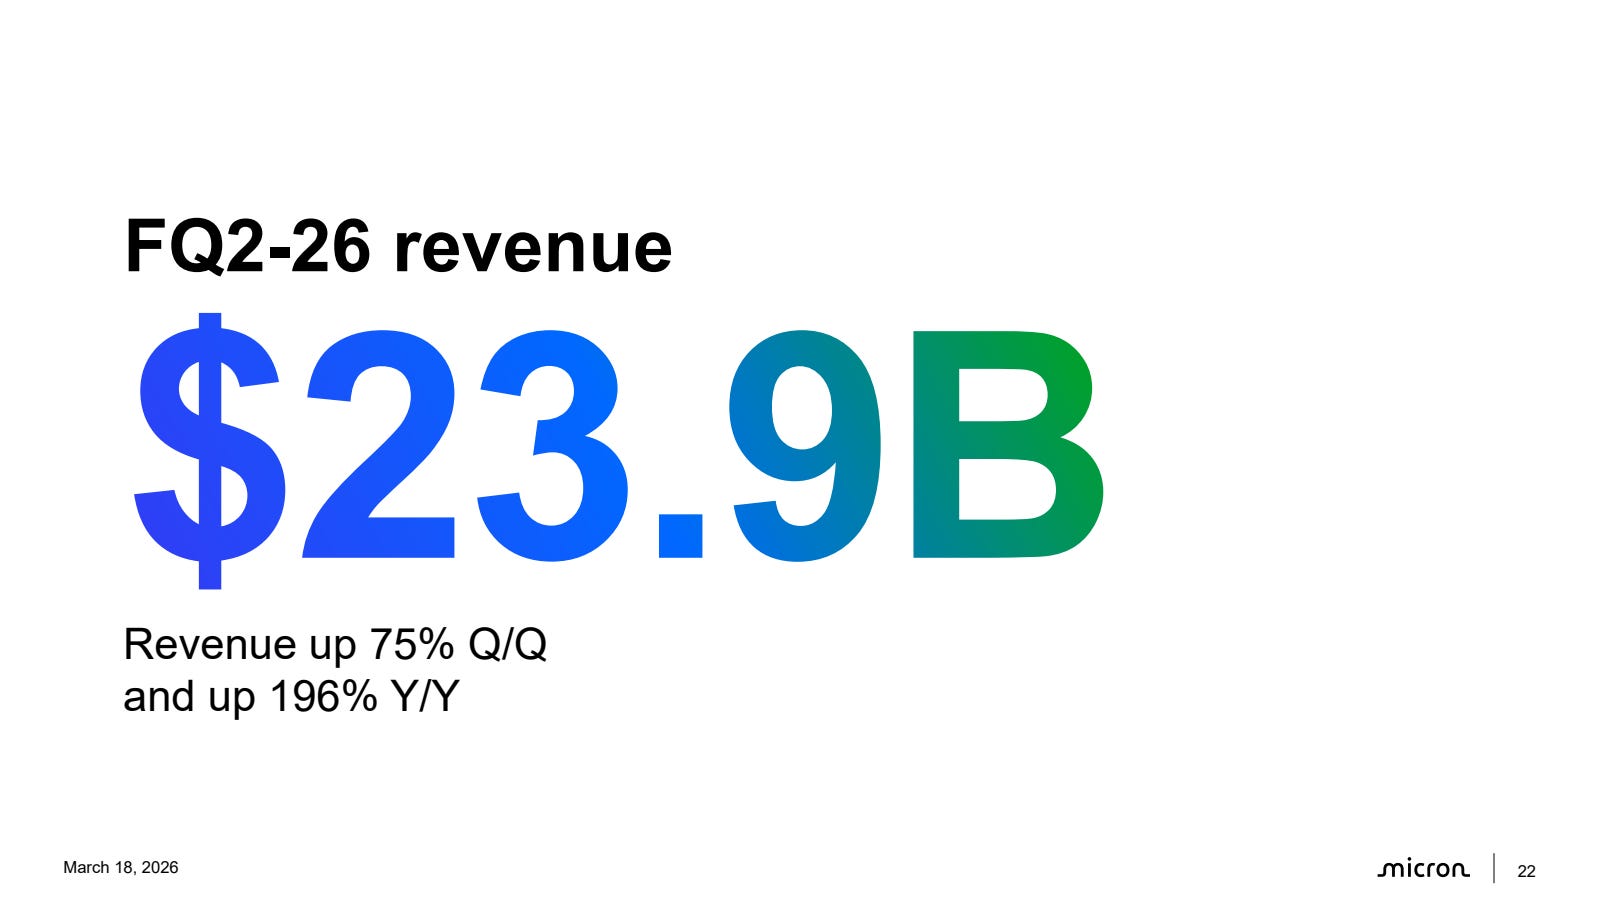
The timing made it sting for investors. TurboQuant landed the same week Micron reported its best quarterly earnings in years. The market had spent months pricing in a structural shortage, and suddenly, a paper from Google suggested the shortage might not matter as much as everyone thought.
But the reaction deserves some scrutiny. TurboQuant compresses the KV cache during inference, meaning it helps when a model is generating a response to you. It does not touch the model’s base weights, the core parameters that define what the model knows. It does not reduce the memory required during training. And it does not change the fact that every new generation of chips is being designed to consume more HBM, not less. The compression applies to one layer of the problem, not the whole stack.
There is also a historical pattern worth considering. Every time the tech industry has found a way to make something more efficient, the result has not been less total demand for the underlying resource. It has been more. When MP3 compression made music files smaller, people did not download fewer songs. They downloaded thousands. When streaming compression made video practical over the internet, the world did not watch less. It built Netflix. The term for this is Jevons’ paradox: efficiency gains lower the cost per unit, which increases usage, which in turn increases total consumption. If TurboQuant works as advertised and makes inference cheaper, the most likely outcome is not that companies use less memory. It is that more companies deploy AI in more places, to more users, with longer conversations, which means aggregate memory demand goes up, not down.
That does not mean software solutions are irrelevant. They buy time, they make inference cheaper at the margins, and they will probably make AI more accessible for smaller teams running models on their own hardware. But consider what the biggest players are actually doing. Google published TurboQuant to reduce memory usage. Google is also locked into long-term supply agreements to buy as much physical memory as it can secure (more on Edgen). The same companies trying to use less memory are simultaneously spending billions to guarantee they have more of it. If the software fix were enough, the hardware scramble would not exist. The fact that both are happening at once tells you everything about how serious the constraint really is.
Where this leaves us
The AI industry talks about computing the way the car industry talks about horsepower. It is the metric that makes headlines, the number that fits on a spec sheet, the thing investors know how to price. But there is an additional constraint underneath the compute race that is arguably just as binding, and it gets a fraction of the attention: how fast the memory can feed the processor.
That constraint is being attacked from every direction. Three companies are spending tens of billions to build more capacity. Researchers are publishing compression algorithms to squeeze more out of existing data. Chip designers are stacking memory higher and wiring it closer to the processor with every new generation. The new fabs under construction could bring meaningful relief by 2028, and if they do, the acute shortage may ease. But even then, the underlying dynamic remains: AI capability scales with memory, which means every generation of models will push the constraint forward again.
It does not matter who wins the chip race. Everyone needs memory. And as El Arte de Invertir podcast put it at the close of its own deep dive on the topic: Nvidia has the name, software companies have the hype, but there are three factories, two in South Korea and one in Idaho, that if they stopped tomorrow would paralyze the progress of artificial intelligence globally. In the history of capitalism, that has always been worth something.
Roberto Mazariegos is an intern at Nido Ventures, where he writes for ConteNIDO. He first encountered the memory bottleneck through his own research and following markets, and has since been tracking the story as both a market and technology question. He writes at the intersection of AI, investing, and the forces reshaping how capital flows through the tech stack.
This article is for informational and educational purposes only and does not constitute investment, financial, or tax advice. The information presented reflects publicly available data and the author's analysis as of the date of publication. Readers should consult a qualified financial advisor before making any investment decisions.